ThinkingCap Qwen3.8 27B on RTX 5090: evidence
This campaign measures one local RTX 5090 through a direct managed vLLM endpoint. The complete AWQ checkpoint includes BF16 vision and MTP weights. Earlier RTX PRO 6000 preparation was a targeting error; no ThinkingCap inference ran there, and that host is outside this evaluation.
Selected configuration
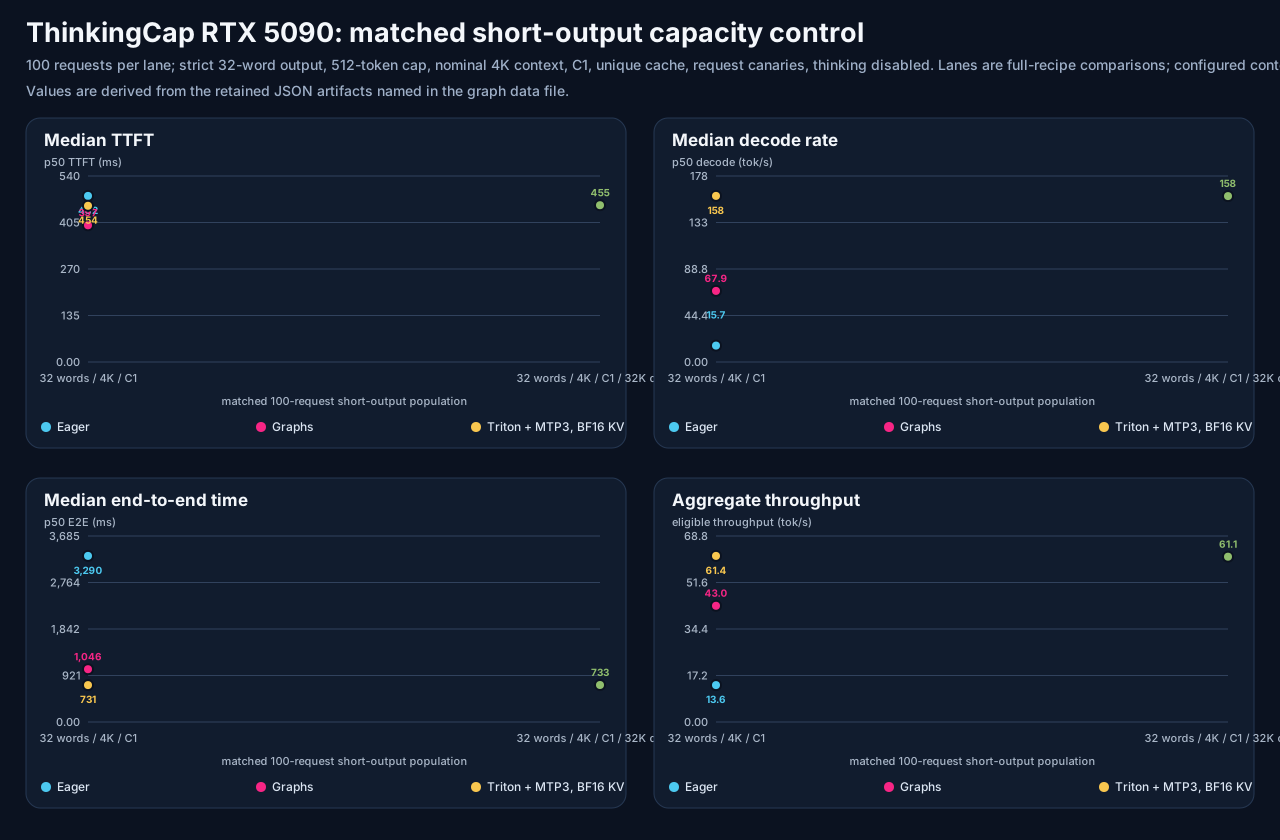
The retained profile is 32K context, C1, target TRITON_ATTN, MTP3, CUDA graphs and BF16 KV, with two-image admission. Its strict 100-request short-output population passed 100/100 at median decode 158.355 tokens/s and median TTFT 455.442 ms. Functional 27/27, reasoning controls 8/8, vision 18/18, repeated ten-question MMLU-Pro diagnostic 30/30, context 60/60 and bounded synthetic agentic 2/2 passed. These are separate bounded workloads, not a full public leaderboard score. Actual near-limit inputs were 29,578-29,629 tokens with a 2,048-token total completion cap; larger context and concurrency remain unmeasured.
Evidence map
- Run plan, cache-expansion plan, coverage and gaps, and campaign state.
- Model identities, source registry, operational source hashes, final source verification, and physical calibration.
- Selected 32K results, native strict capacity, and public recipe.
- Context results and agentic results, with native job artifacts and redaction ledgers under their evidence roots.
- Incumbent baseline, initial startup failure, and successful WSL recovery.
- Eager capacity, graph capacity, and Triton BF16 16K results.
- Flash-target MTP results: strict capacity 99/100 is aggregate-ineligible. Triton FP8 cache results: capacity passed but repeated quality 27/30 failed; rejected for selection.
- Machine-derived chart, chart data, and graph manifest. The chart compares complete recipes; it does not isolate MTP speedup.
- V2/FP8 source review, context plan review, context-runner boundaries, and cache-capacity interpretation.
- GPU telemetry, final HTTP observations, and verified ending state.
- Friction and fixes, sampling limitation, final repository validation, and Windows Pi failure investigation.
- Decision summary, artifact ledger, and publication summary.
Interpretation
Native failed runs remain failed. The first eager preflight was accidentally overwritten; the retained preflight is functional-only. Other runs use unique output files and one inference client at a time. Redaction ledgers retain original and published hashes; operator identities are sanitized while schemas and numeric observations remain intact. Embedded native job hashes identify original private artifacts; the publication ledgers separately bind sanitized bytes. Some early exports normalized the actual loopback port to a generic port, as their ledgers record. No token or credential is retained.
The required full Python repository gate failed in an unrelated Windows Pi smoke test; that failure and its deferred fix are retained. It does not change the passed model gates. Direct candidate retention was authorized by the user; route/client alias promotion is outside this campaign.
Independent review accepted the bounded model qualification. Publication closure records artifact-ledger completion and the separately deferred repository failure.
Publication privacy correction
Before merge on 2026-09-24, remaining operator container IDs were replaced with stable synthetic labels, and a generated non-secret RPC command ID in a historical test-failure log was redacted. The additional redaction ledger records the prior sealed-manifest hash and exact per-file hash transition. Measurements and campaign decisions are unchanged; the manifest now binds the sanitized publication bytes.