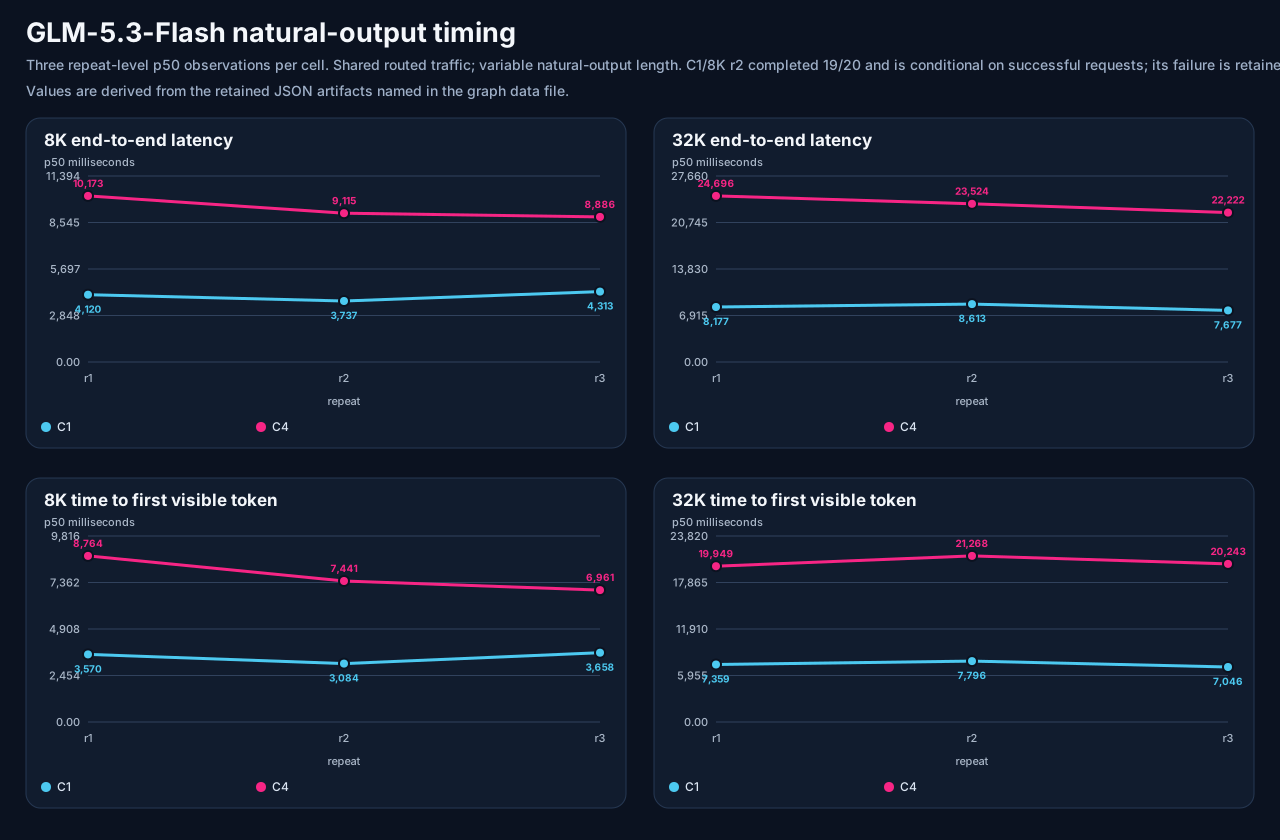
2026-10-16 GLM-5.3-Flash natural-output baseline
Decision: no-promotion. This is an observational baseline for the current
GLM-5.3-Flash r11 route. It measures natural-output timing and a
limited independently graded coding repeat. It does not requalify the incumbent
and does not select, reject, or promote a replacement.
Result card
The current GLM-5.3-Flash r11 route completed 239 of 240 natural-output requests across 12 cells at nominal 8K and 32K contexts, C1 and C4. The table reports the median of three run-level medians and their range. One C1/8K request exhausted its 16,384-token cap without visible output after 213.753 seconds. The cached five-task coding set was attempted twice. R1 resolved 4/5 with complete grading; R2 resolved 0/2 graded patches and exhausted the 60-step limit on three empty, ungraded submissions. Coding repeatability was not established. These are ten attempts across five reused identities, not a fresh held-out score. The router remained shared, and no model, route, or serving configuration changed.
Configuration
The measured hardware was two NVIDIA RTX PRO 6000 Blackwell Max-Q GPUs (97,887 MiB reported per GPU). The incumbent uses EXL3 4 bpw weights, FP8 KV, TP2/DCP1, automatic prefix caching and no speculation. Its configured context is 327,680 tokens and scheduler concurrency is four; these are configuration values, not context-capacity results from this campaign.
Configuration identity
pins brandonmusic/GLM-5.3-Flash-tr3-4bpw, its exact revision, engine revision,
and immutable runtime image digest. The benchmark producer remains frozen at
e267df90fdc7d6a99cc1904f8a4be466cf63d8ed for matched challenger runs. The
workload manifest
records sampling, cache policy, configured coding limits and plan bindings.
What this baseline measures
- Natural-output timing used unique prompt bytes for each request under the incumbent routed policy: temperature 0.6, top-p 0.95, maximum reasoning effort, and a 16,384-token caller cap. Generated output length was not held constant.
TTFOis request start to the first reasoning or visible-content delta.TTFTis request start to the first visible-content delta. E2E is request start to terminal stream observation. Completion-token counts may include reasoning tokens; the evidence cannot separate visible and reasoning tokens.- The timing runner requires visible output and terminal observation. It does
not prove a
stopfinish reason or semantic correctness for each response. - Five previously cached SWE tasks were each attempted twice. The pinned independent grader evaluated submitted patches. This avoided pulling uncached images while the volume reserve is constrained. It is not the planned ten-task fresh, held-out baseline.
Results
| concurrency | nominal context | repeats | completed / attempted | E2E p50, repeat-median range | TTFO p50, repeat-median range | TTFT p50, repeat-median range | combined-completion decode p50, repeat-median range | actual prompt p50 | completion p50 |
|---|---|---|---|---|---|---|---|---|---|
| 1 | 8,192 | 3 | 59 / 60 | 4,120 ms [3,737–4,313] | 1,315 ms [1,297–1,317] | 3,570 ms [3,084–3,658] | 68.22 tok/s [68.01–76.85] | 6,072 | 209 |
| 4 | 8,192 | 3 | 60 / 60 | 9,115 ms [8,886–10,173] | 1,357 ms [1,317–4,276] | 7,441 ms [6,961–8,764] | 32.22 tok/s [32.10–36.33] | 6,072 | 218 |
| 1 | 32,768 | 3 | 60 / 60 | 8,177 ms [7,677–8,613] | 5,141 ms [5,065–5,143] | 7,359 ms [7,046–7,796] | 68.12 tok/s [68.03–76.92] | 25,285 | 206 |
| 4 | 32,768 | 3 | 60 / 60 | 23,524 ms [22,222–24,696] | 11,305 ms [5,232–12,010] | 20,243 ms [19,949–21,268] | 18.61 tok/s [13.42–23.48] | 25,285 | 227 |
| coding population | independent grading | resolved / graded / attempted | interpretation |
|---|---|---|---|
| five reused pinned tasks, two serial repeats | R1 complete 5/5; R2 incomplete 2/5 | R1 4/5; R2 0/2 graded plus three step-limit failures | repeatability not established; no pooled score or fresh held-out claim |
| pinned task | R1 | R2 |
|---|---|---|
sphinx-doc__sphinx-9658 |
resolved | submitted, graded unresolved |
sympy__sympy-12096 |
resolved | step limit, empty patch, ungraded |
django__django-13512 |
resolved | submitted, graded unresolved |
pydata__xarray-4356 |
resolved | step limit, empty patch, ungraded |
pylint-dev__pylint-8898 |
submitted, graded unresolved | step limit, empty patch, ungraded |
Limits
- This is shared-router client observation. The workload snapshot was unavailable, so the campaign does not claim traffic isolation or engine-only throughput.
- Storage preflight passed with 109,701,644,288 bytes available. A separate post-run check at 2026-10-17T03:21:20Z measured 88,034,181,120 bytes (about 82 GiB), below the 100 GiB trial-admission reserve. The cause is unproven and is not attributed to the coding failures. No cleanup or pruning was performed. The measurement campaign is closed; storage resource closure remains open and further trials require the reserve to be restored.
- Natural output has variable length. Combined completion-token decode rates are workload-specific and may include reasoning tokens; they are not controlled-decode equivalence or visible-only token speed.
- Twenty requests per cell and three repeats support per-cell medians and their ranges. They do not support a stable p99, service-level tail, or service-stability claim.
- A single C1/32K request in each of r1 and r2 generated unusually long reasoning traces (193.449 and 223.058 seconds E2E). They remain retained as descriptive maxima, without attributing them solely to the model or shared traffic.
- Nominal context is a request target. The table includes endpoint-reported actual prompt counts; nominal 8K and 32K are not measured context validation.
- The earlier strict 128-
coderesponse gate remains historical diagnostic evidence. It is excluded from replacement ranking because it failed across the compared models and does not represent the user workload. This campaign does not erase, reinterpret, or convert that failure into a pass.
Evidence and publication boundary
Public evidence includes the bundle README, common manifest, timing graph, graph data, final coding summary, and independent R2 review.
The index links all twelve native timing artifacts, both native SWE artifacts,
official grading reports, failure records and post-run continuity evidence.
Private work directories and raw logs remain retained privately; no cleanup was performed.
Evidence labels are functional
and observational capacity; decision labels are current (incumbent
continuity) and no-promotion. This campaign proposes no promotion. R2 covers the full planned attempt set but official grading is incomplete; full SWE-interval retry and server telemetry remain unknown. A parallel low-priority CPU task overlapped the run; it is retained as a shared-host limitation without a causal claim.