Voice model results
Compare speech recognition, speech generation and the answer model as separate parts of a voice assistant. This page collects the dated local comparisons and their deployment decisions. Each finding retains exact checkpoints, runtime settings, failed trials and raw evidence.
Latest comparison: English on Apple M4 Max
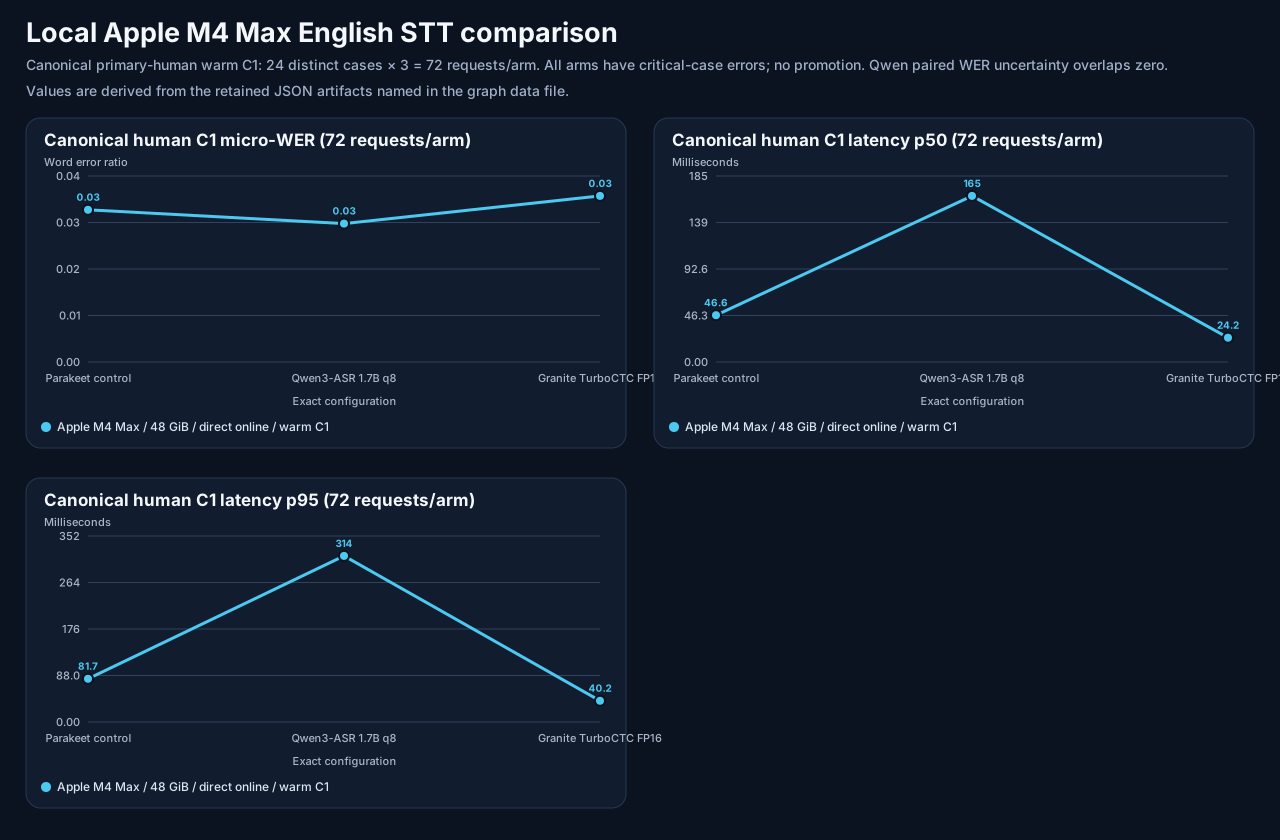
The October 6, 2026 campaign tested a quality-first personal, noncommercial assistant on a 48 GiB Apple M4 Max laptop. No replacement qualified for promotion. The existing Parakeet Metal, Kokoro MPS and Qwen3-4B MLX components were retained without claiming a new full qualification of those controls.
| Component | Models compared | Result |
|---|---|---|
| Speech recognition | Parakeet TDT 0.6B v3, Qwen3-ASR 1.7B 8-bit, Granite Speech TurboCTC FP16 | Qwen's small paired accuracy improvement was inconclusive; Granite had worse accuracy. Critical title fidelity remained unresolved. |
| Speech generation | Kokoro, Breeze TTS 2 BF16 and 8-bit, Fish S2 Pro 8-bit | Breeze had unresolved critical speech-fidelity issues. BF16 Breeze and Fish hit resource guards. Retain Kokoro. |
| Answer model | Qwen3-4B, Qwen3.5-9B and Qwen3.8-27B 4-bit, including separate off/low/medium profiles | The 27B low and medium profiles each passed 144/144 semantic answers, but failed strict format and capacity gates. Retain Qwen3-4B. |
The profiles have different reasoning and output budgets. These are whole configuration comparisons, not an equal-compute intelligence ranking. ASR transcripts of generated speech are a fidelity diagnostic, not a substitute for human listening. First complete PCM-frame latency is an HTTP measurement, not acoustic playback latency.
Read the complete finding · Inspect the human-only STT chart · Browse every tested profile · Open the hardware record
What still needs validation
Human listening and blind preference, the user's microphone and accent/noise coverage, real client deadlines/reconnect/cancellation, and physical playback interruption remain open. The conditional replacement soak did not run because no exact replacement passed the component gates. Bounded restoration checks passed; they do not establish a full end-to-end qualification or continuous monitoring. The campaign also retains the failed full Mac source-test gate.
Follow future comparisons
New campaigns belong in the dated findings, run catalog, model dossiers and measured hardware record. Keep this page as the reader's entry point, and retain older findings when a later experiment changes the recommendation.
For operation and reproduction, use the voice guide, native MLX audio runtime and repeatable campaign guide.