ThinkingCap Qwen3.8 27B AWQ on RTX 5090
Date: 2026-09-24
Decision: no-promotion. The selected bounded configuration is Triton + MTP3 with BF16 KV at 32K/C1 on one RTX 5090. No route, client alias, or deployed-topology change occurred.
Result card
The selected 32K/C1 direct configuration completed its bounded functional, quality, capacity, context, and agentic contract. It is not a promotion or universal-context result.
| Setup | Qualified value |
|---|---|
| Model | bottlecapai/ThinkingCap-Qwen3.8-27B-NVFP4A4-AWQ@f8fe157f207a13f977bc3d620ce10a3e9ba5ab11 |
| Hardware | one RTX 5090; direct managed endpoint |
| Runtime | vLLM 0.29.0; target TRITON_ATTN; BF16 KV; MTP3 |
| Recipe | 32K selected snapshot |
| Contract | 32K API context, C1, two images about 1 MP, zero video |
| Decision | no-promotion |
| Headline measurement | Local result | Conditions |
|---|---|---|
| Median TTFT | 455.4421 ms | n=100 strict 32-word, nominal 4K, C1 |
| Median decode | 158.355179 tok/s | same population |
| Aggregate throughput | 61.14585 tok/s | same eligible population |
| Context | 60/60 passed | actual 8,198-8,229 and 29,578-29,629 tokens |
| Agentic smoke | 2/2 passed | six API turns, four tool calls |
Why it matters: The selected direct lane retained a clean 32K/C1 contract with bounded context and tool-use evidence.
Important caveat: This does not establish C2, SWE, soak, video, or maximum possible context.
Artifact ledger · Evidence index · 32K result · context · agentic
Outcome and decision
The selected 32K BF16 Triton + MTP3 lane passed 27 functional checks, 8 thinking checks, 18/18 image attempts, 30/30 limited MMLU diagnostic attempts, and 100/100 strict capacity requests. The final managed state retained the exact pinned model/image, healthy HTTP status, and 32K served identity. Final telemetry recorded 3,342 MiB free. The prior Qwen was stopped; caches were retained. The selected candidate remains running under explicit user authorization, verified by managed and HTTP ending-state checks. No route/client promotion occurred. Complete local weights comprise 26 files (23,447,947,228 bytes), including the BF16 vision tower and MTP weights.
Exact configuration
The selected recipe is the retained 32K BF16 snapshot. Its 32K API contract uses C1, target Triton attention, BF16 KV, and standard V2 MTP3 inheritance. The quality diagnostic budget is total 10,240 tokens: 8,192 reasoning plus 2,048 visible output, not a 10,240 visible budget.
The runtime image is vllm/vllm-openai:v0.29.0@sha256:082ca6f035279109041ffd3fe0695cb568b29bc580b35c4f297a66a08b216c1b, engine revision 98dff2a81d747d1dba01a47f939f48c3526d4206. Measured hardware is one 32,607 MiB RTX 5090 (sm120), driver 616.92, on Windows with Docker Desktop Linux/WSL2. The recipe uses TP1, GPU fraction 0.87, 1,024 batched tokens, CUDA graphs, prefix caching off, and explicit WSL pin memory. Weights remain NVFP4 W4A4 AWQ with mixed FP8/BF16 components; BF16 KV describes the cache, not full-precision model weights.
Method
Capacity uses 100 unique-cache, canary-controlled strict 32-word requests at nominal 4K/C1: actual inputs 3,609-3,687 tokens, 45 completion tokens per request, max output 512, thinking disabled. The serving process was warm, prefix caching disabled, and the first measured request retained. This uncontended population measures short controlled output, not general-chat speed. Context uses five deterministic cases, two requested-input buckets, three needle positions and two repetitions (60 observations), with model-default reasoning and a 2,048-token total completion cap. The configured maximum 32,768 is not a tested 32,768-token input. CPU documentation checks overlapped context and functional/quality tests, so their latencies are diagnostic only. Agentic smoke uses two cases, six API turns, and four tool calls. Functional and quality results are behavior evidence; the retained 32K capacity run is the timing population.
Results
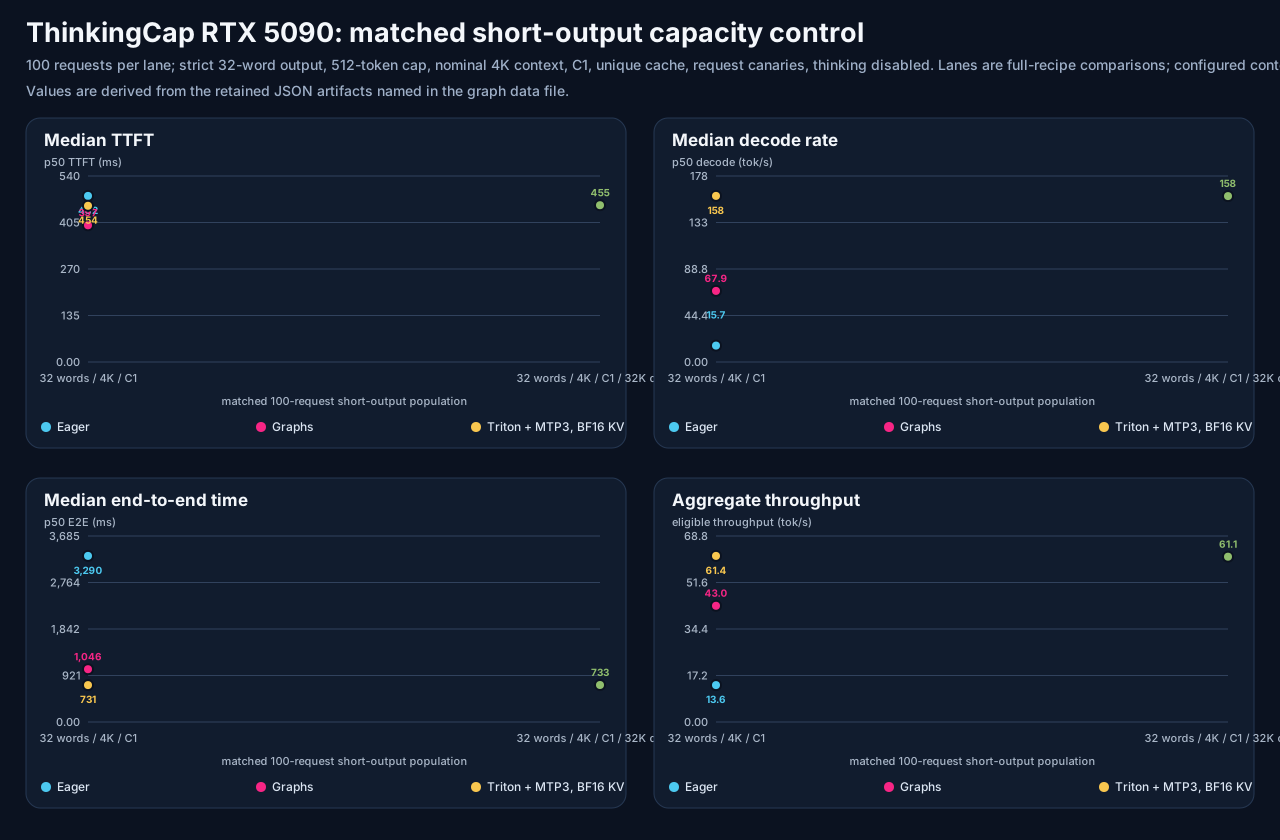
The selected capacity artifact reports 455.4421 ms median TTFT, 158.355179 tok/s median decode, and 61.14585 tok/s aggregate throughput. Context passed 60/60 with stop finishes at the retained actual-token ranges. Agentic passed 2/2; all terminal responses were tool_calls or stop, and zero reasoning was observed. See capacity, context, and agentic.
Configuration comparison
| Complete recipe | Configured context | Strict requests | Median decode tokens/s |
|---|---|---|---|
| Eager, no speculation, BF16 KV | 16K | 100/100 | 15.673 |
| Flash attention, graphs, no speculation, BF16 KV | 16K | 100/100 | 67.868 |
| Triton, graphs, MTP3, BF16 KV | 16K | 100/100 | 158.496 |
| Selected Triton, graphs, MTP3, BF16 KV | 32K | 100/100 | 158.355 |
The chart and machine-derived data bind these values to native artifacts. There is no matched Triton/no-speculation arm, so these are whole-recipe results and do not isolate MTP speedup. Nominal 4K input and controlled output are shared; configured context differs for the selected profile.
Failures and caveats
Earlier eager and graph lanes remain retained comparison history. Earlier Flash-target MTP was 99/100 strict and is performance-ineligible. Triton + MTP3 FP8 passed function and capacity but failed the required quality gate 27/30 after three reasoning-budget exhaustions; it is rejected and its 56K lane was not run. The full repository gate retained one unrelated Windows Pi RPC failure: 7,923 passed, 417 skipped, one failed. The exploratory source patch was reverted; runtime and test code are unchanged. See validation and product gap.
The MMLU-Pro result is ten questions repeated three times at temperature zero, not a full benchmark score. No matched BF16-weight reference was tested. GPU telemetry sampled every five seconds; selected-profile minimum free memory was 3,342 MiB, below the initial 4 GiB reserve assumption, with sampled peaks of 478.03 W and 66 C. These samples include desktop/driver use and may miss peaks; there is no energy-per-token claim. See telemetry.
What to test next
C2, SWE, long-duration soak, video, and any expanded context require separate evidence. They are not required for this bounded 32K/C1 direct qualification.
Evidence boundary
This qualifies the stated 32K/C1 direct configuration only. It does not claim universal maximum context, production routing, promotion, or a general quality ranking.