Qwen3.8 efficient variants on RTX 5090 benchmark evidence
This directory contains the sanitized evidence bundle for the dated finding. The native benchmark artifacts remain authoritative; the files below provide a consistent campaign-level index.
Campaign boundary
- Campaign ID:
2026-09-12-qwen38-efficient-variants-rtx5090 - Capability: text and tools
- Repository revision:
948346f5ab553361c6b61d9517b71a0e5e3cfe98; clean isolated worktree at start - Evidence labels: functional and diagnostic quality; failed strict capacity retained
- Decision labels: incumbent retained; challengers no-promotion
- Promotion boundary: operator authorized selection and promotion, but no challenger cleared replacement gates
Common campaign artifacts
artifact-manifest.json- role ledger, native schemas, file hashes, and explicit gapssource-registry.json- dated source provenance and decision impactsummary.json- bounded machine-readable outcome and decisionfriction-log.md- failures, workarounds, ambiguity, and recurring manual stepsrestoration.json- starting/ending state and post-run verification, or the reason restoration was not applicable
Working campaign controls
campaign-state.json- compact resumable stage, launcher, assignment, completed-cell, and next-action ledgerdispatch-packet.md- bounded task packet for a delegated campaign stagecoverage-and-gaps.md- request-to-evidence matrix that keeps partial, rejected, and missing outcomes visible
These controls organize execution. They become evidence only when the final artifact manifest retains them under an applicable role.
Workload and plan
workload-manifest.json— built-in deterministic workload and controlsrun-plan.json— predeclared order, gates, budgets, and 50 percent usage stopconfiguration.json— sanitized starting hardware and incumbent identityfeasibility-input.json— interval screen before downloads or loads- Managed recipes — byte-identical public copy of the four exact candidates in
configs/qwen38-efficient-rtx5090-recipes.toml
Raw run evidence
| Profile | Functional gate | Thinking-enabled diagnostic |
|---|---|---|
| Signal Q6_K MTP3 | Preflight | 9/10 strict |
| Swift Q6_K MTP3 | Preflight | 9/10 strict |
| Qwopus Flash Q6_K no-spec | Preflight | 1/10 strict |
| Minitron20B Q6_K no-spec | Preflight | 3/10 strict |
| Incumbent UD-Q4_K_XL MTP3 | Restored preflight | 8/10 strict |
These ten-question, one-repeat scores include exact format and completion failures; they are not general knowledge benchmark scores. Native artifacts retain complete visible outputs, reasoning metadata, finish reasons and keys. See workload, errata, lifecycle review, recipes, and matched no-spec controls.
Decision and publication
Retain the exact healthy262K incumbent. Signal is the best new efficiency research lead, but its tested64K profiles did not qualify as replacements. Thinking-off repeated results: Signal24/30, Qwopus24/30, Minitron15/30, and incumbent21/30. These repeat the same ten questions, not30 independent questions. The Signal9216-token retry also exhausted reasoning without a final answer.
The cold32-word diagnostic chart and hash-bound data show successful N5 populations only. Swift's warm and Minitron's failed populations are excluded. Context, weight quantization and speculation differ, and CPU load was uncontrolled; the plot is not a finalist or causal speedup claim.
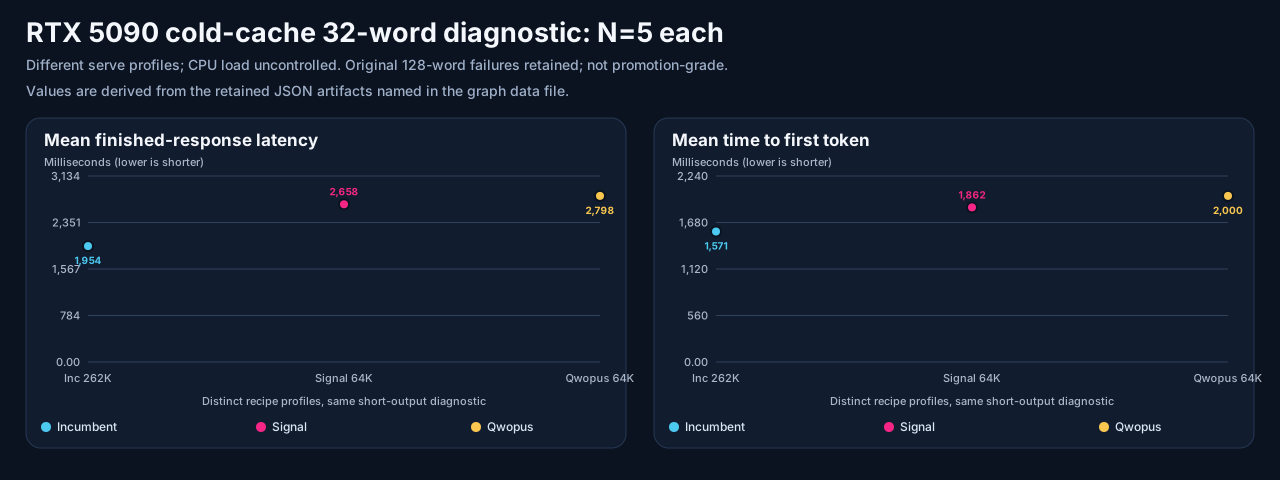
See the dated finding, publication summary, restored state, recovery admission, and Pi review. The common role ledger retains all failed and successful native artifacts; no raw result was rewritten to manufacture a pass.
Repository and publication verification records the 8,117-pass full regression, documentation gates and checkout-byte safeguards. This does not remove the separate general lifecycle release hold. The independent evidence review accepts the bounded decision, subject to exact final manifest integrity.